More at Once. Less Waiting.
Greater concurrency enables more requests to run simultaneously with less queuing.
One API to scale your AI business.
with enterprise-grade scale, reliable performance, and lower costs.




Plan capacity and credit around your workload.
Greater concurrency enables more requests to run simultaneously with less queuing.
Tailored credit terms give your business more room to grow.
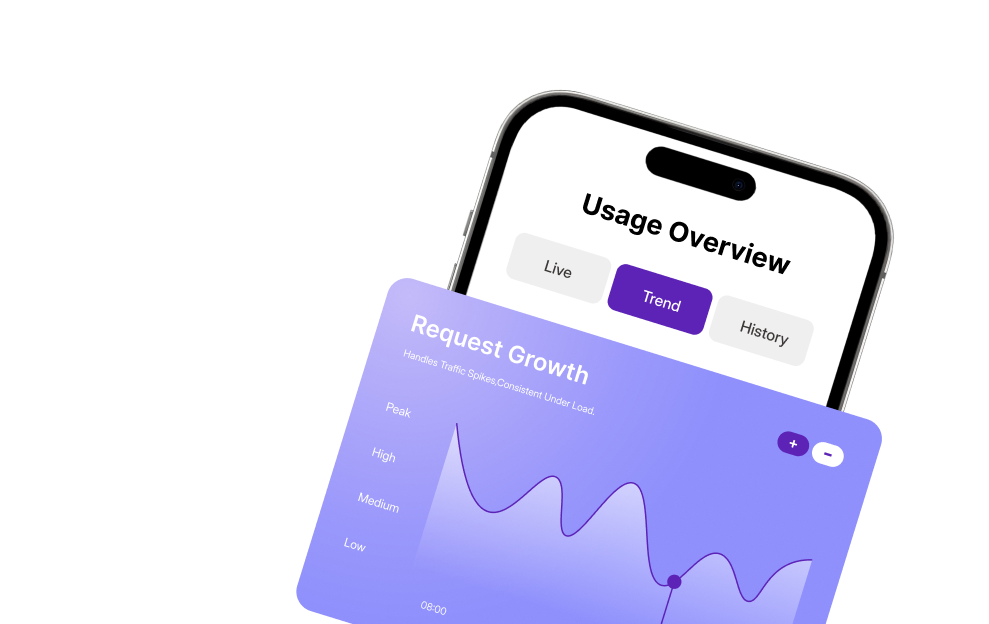
Higher request limits keep your applications moving as traffic grows.
Higher token throughput supports demanding AI workloads at scale.
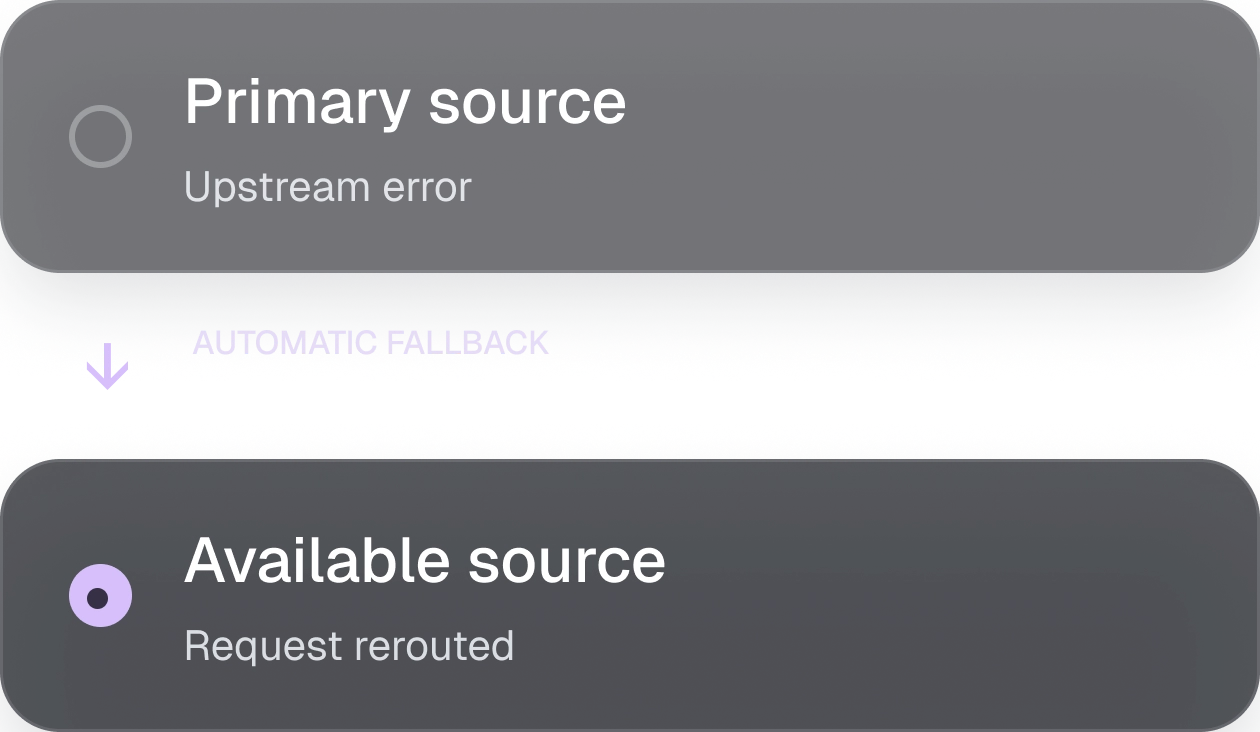
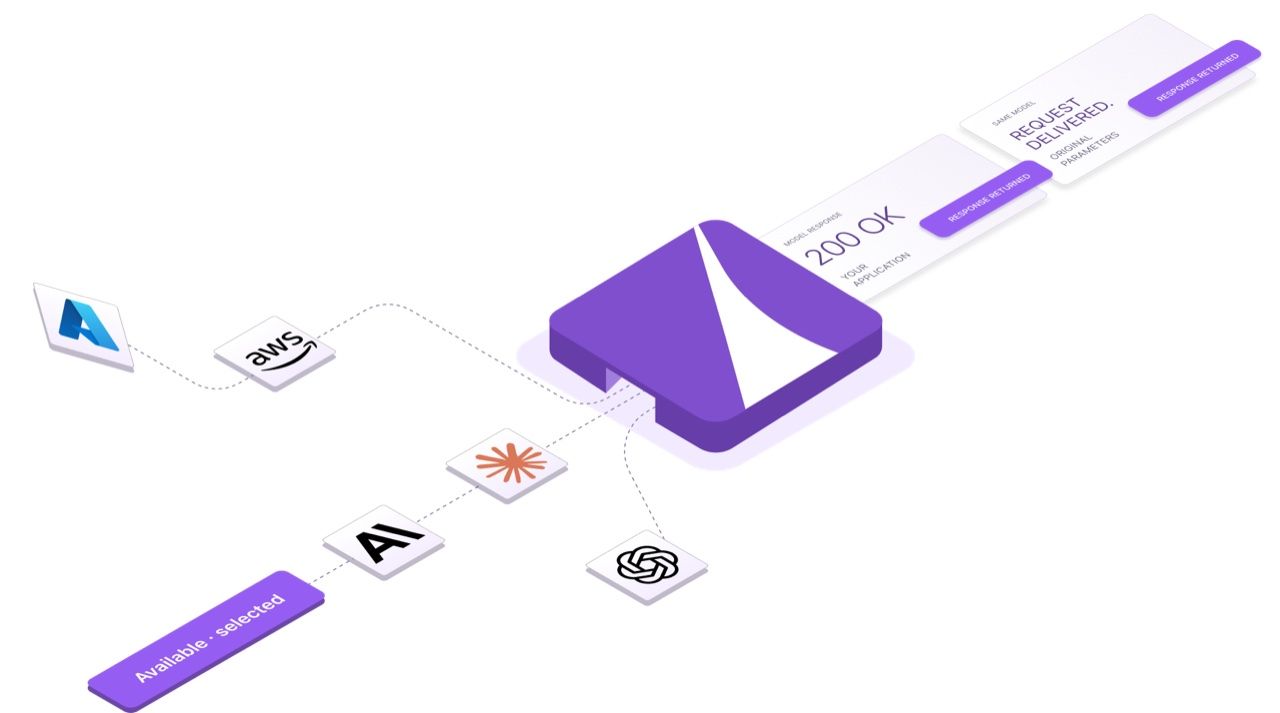
We bring upstream resources together. When one source fails,
your request automatically switches to an available route.
SAME MODEL. LOWER COST.
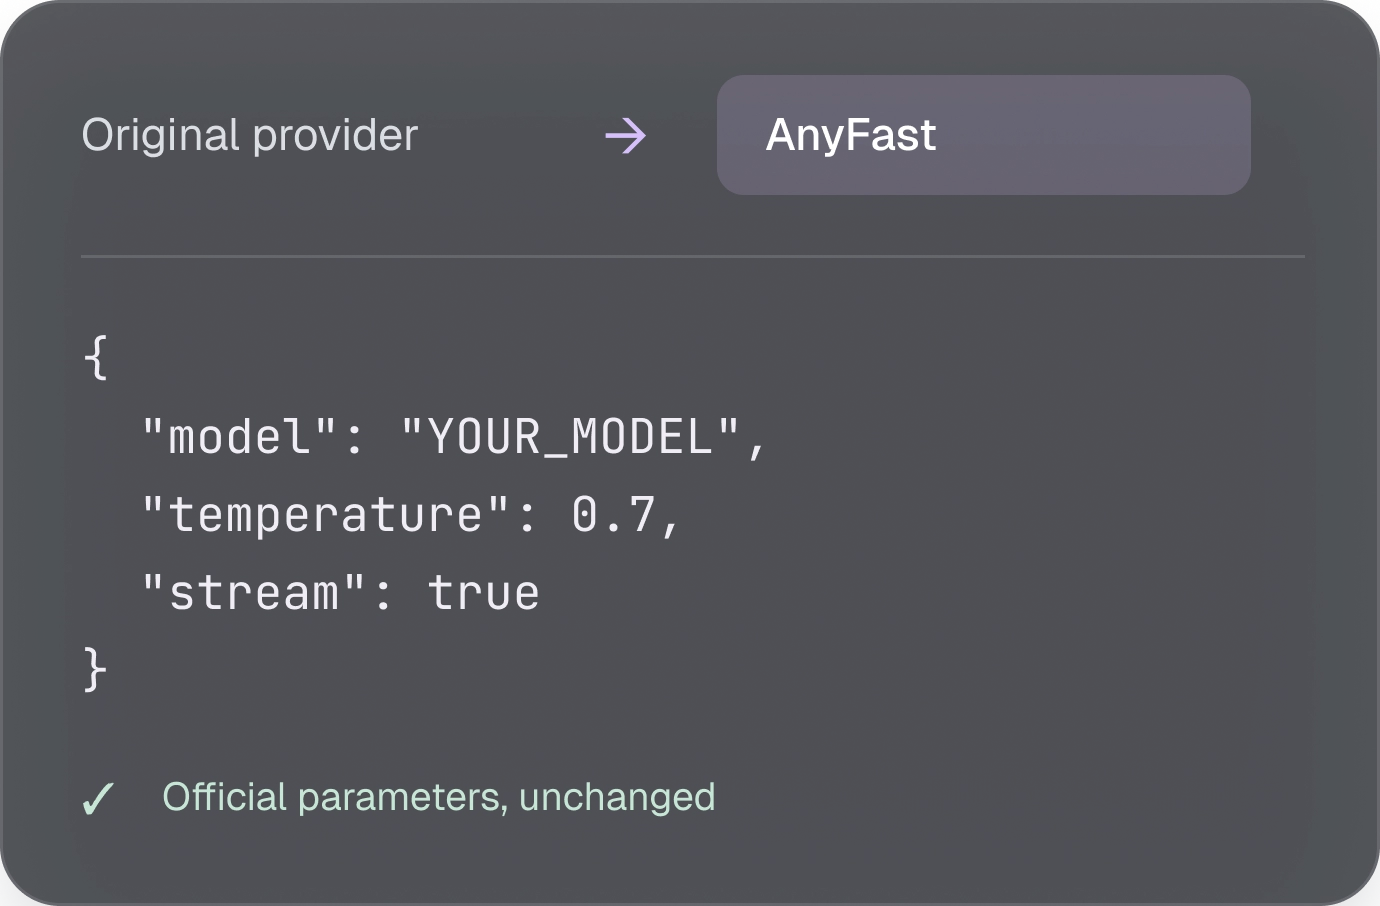
OFFICIAL PARAMETERS ✓
SAME MODEL. LOWER COST.
OFFICIAL PARAMETERS ✓
YOUR BUDGET
More room
to build.
Compare model providers.
Choose the price that works for you.
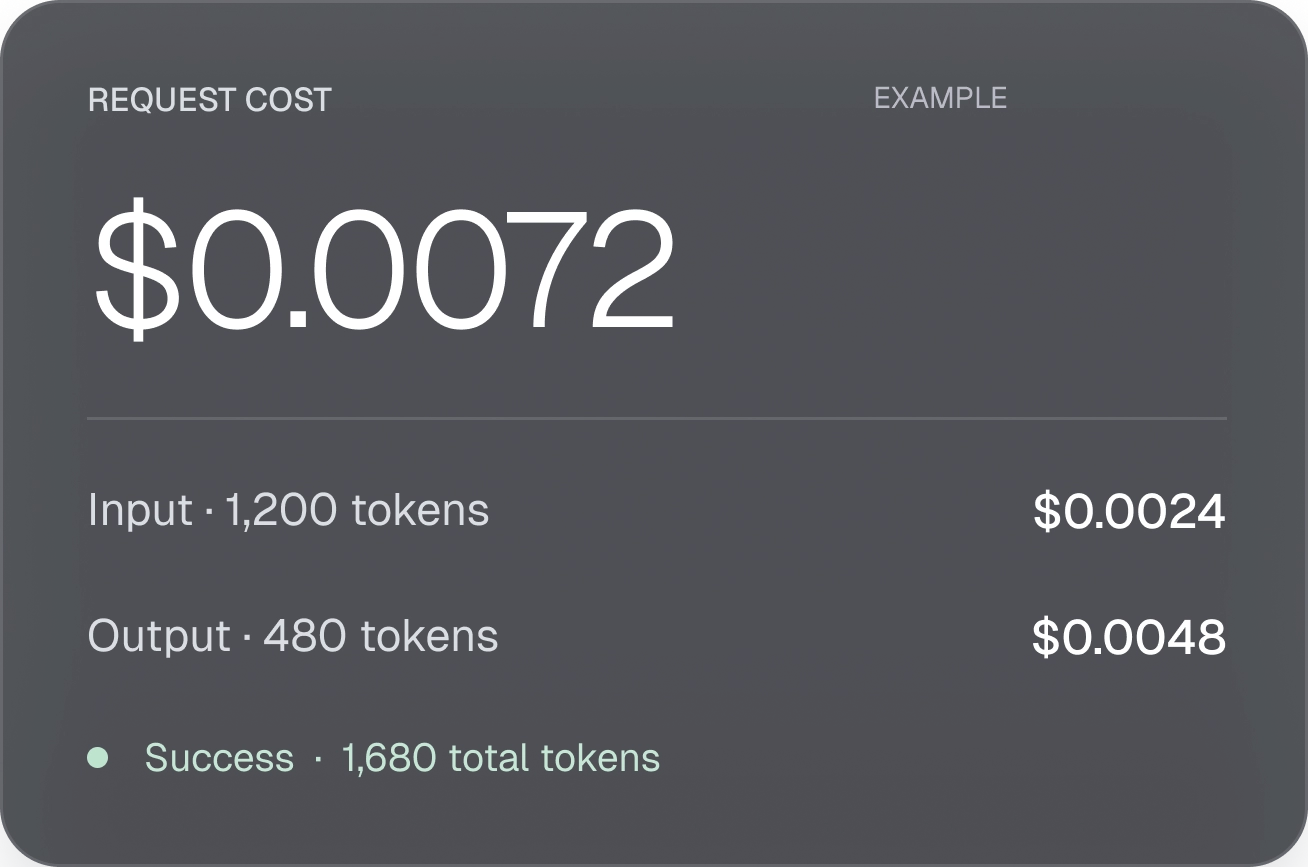
Choose a lower-cost source without changing your model or official API parameters. Spend more on your product.
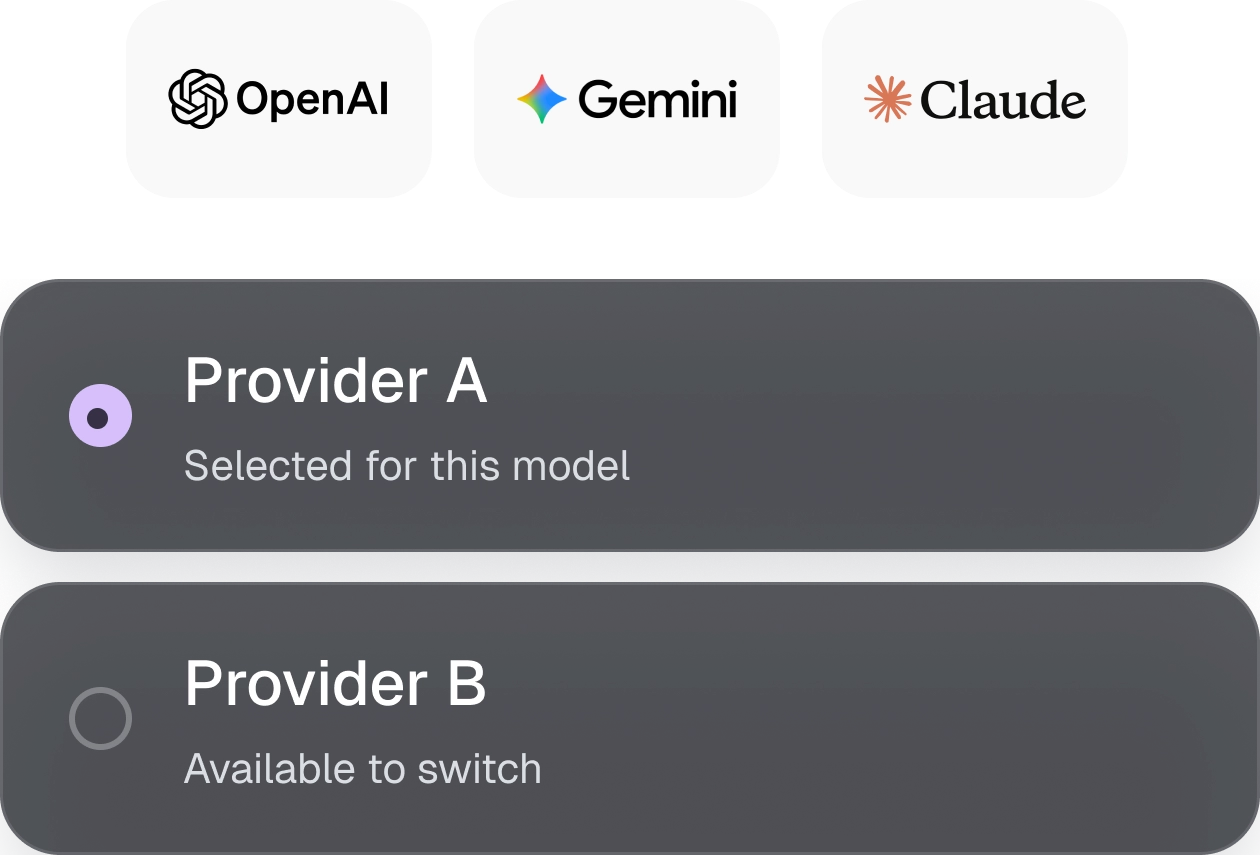
Select the provider and resource channel that fit your workload. Keep control over where requests go.
Errors do not have to become dead ends. Automatically route failed requests to an available source.
Detailed model billing logs and call analytics give you a clear picture of usage, request outcomes, and spend.
Keep the official parameter definitions for every model. Move between original providers and AnyFast without rebuilding the request body.
Less setup. More building.
One API. Every model. Built fast.
We're here to answer your questions and support your needs, anytime.
Flexible AI solutions designed around your unique business needs.
Connect with our experts to find the right solution for your business.

Scale your AI workloads with flexible token limits, higher request capacity, and reliable concurrency for seamless performance.

Flexible billing cycles and tailored credit terms help enterprises optimize cash flow and scale with confidence.

Access leading AI models from multiple providers through one unified API, simplifying integration and enabling greater flexibility.